The hardest telemetry-cost question often arrives after data has been reduced: can an investigation still obtain the evidence it needs? Grafana’s Adaptive Telemetry update separates three concerns—allocating the retention budget, preserving examples of rare behavior, and providing a limited recovery path for some dropped data. The interesting development is that retention policies increasingly express investigative needs. Bytes saved are only one outcome.
Original: Break the link between data volume and your observability bill with Adaptive Telemetry
JK Basra, Steven Dungan · Grafana Labs · 2026-10-20
The same percentage can preserve different information
When one service produces most requests, uniform probabilistic sampling also allocates most retained space to that service. The engineering consequence is many similar health-check records alongside few examples of an infrequently used critical path. Coverage of behavior matters as well as volume.
The volumetric sampling documentation describes grouping by span attributes and continuously adjusting group sampling rates so retained volume converges toward a configured percentage. Crucially, that percentage targets bytes, not trace counts. The same percentage can retain different numbers of traces. The policy improves representation of low-volume groups without promising complete capture.
After adoption, raw retained-trace counts should not be used directly to compare services’ request volumes. Different groups now have different chances of entering the sample. Seeing rare paths for diagnosis and estimating their true frequency are distinct objectives. Improving the former does not automatically produce an unbiased estimate of the latter.
Rare paths need baseline coverage
Diversity sampling constructs fingerprints from attributes such as service, route, and status code, retaining at least one trace per fingerprint every 15 minutes. It adds diversity: even an uncommon request pattern can leave an inspectable example.
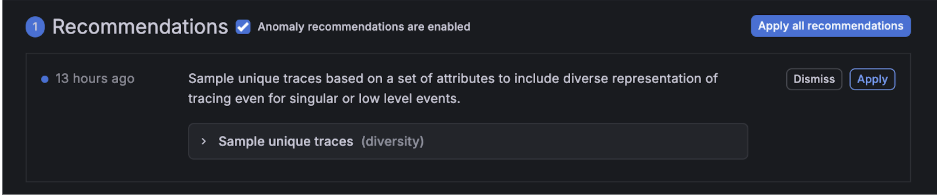
The recommendation preserves examples of distinct attribute combinations. It shows the policy entry point, not a promise to retain every request.
One representative example can expose a new path, but cannot describe its latency distribution or every failure mode within the same fingerprint. The same route and status code can conceal different internal causes. Treat fingerprints as finite classification rules, not complete semantics of system behavior. Combined policies also mean total retained volume need not decline linearly with the global sampling percentage.
Recovery has a deadline and an entry condition
The dropped-trace documentation provides a useful recovery window: for 24 hours after ingest, an unsampled trace can be retrieved by trace ID. Its first retrieval writes it to Tempo; traces not retrieved within the window are eventually discarded. Subsequent search visibility remains best-effort. The reliable entry point is the known ID, and very large traces may be returned with truncation markers.
Whether logs, error reports, or support tickets retain the trace ID directly determines the value of this capability. An investigation that only knows a region became slow last night cannot substitute this lookup mechanism for attribute-based search. An incident discovered days later has also missed the 24-hour window. The feature reduces one class of sampling loss without restoring indefinitely searchable full-fidelity history.
Logs and metrics introduce different trade-offs
The article also describes log archives in customer-owned object storage and automatic application of metric recommendations. Log Archive and collector-side filtering are in public preview, while Replay is still forthcoming. An archive’s existence does not establish an available end-to-end replay workflow. Recovery latency, object-storage charges, and retention policies require separate assessment. Official update
The Auto-Apply documentation distinguishes Coverage-first from Cost-first. The former can restore detail to accommodate new query needs; the latter constrains recommendations using series-count estimates from the latest analysis. Cost-first does not compare live counts before and after changes, nor guarantee that counts never grow. Define exemptions for critical metrics before enabling automatic application in selected segments.
From an engineering perspective, a lack of recent queries only establishes limited observed demand. A rare audit or disaster-recovery question may not yet have occurred. Automation should reduce repetitive review while retaining a way to express exceptional requirements. Otherwise it may remove precisely the dimensions needed by a future incident.
Retention policies change diagnostic inputs
For anomaly detection or agent investigations, the sampler is part of the data-generating process. More retained traces of one type after a policy change may reflect a greater retention probability, rather than a busier service. Preserve policy versions and change times when comparing outcomes, or a model may interpret a sampling change as a workload change.
A useful evaluation can start with a predetermined set of fault cases. Identify what each originally required: a complete call chain, an error code, an infrequent log message, or a high-cardinality label. Then check whether the policy retains the distinctions needed to identify causes. Even an unchanged sample count can conceal the loss of a critical association.
Include both common and uncommon incidents. Common faults readily demonstrate continuing usefulness; rare faults better test baseline coverage and recovery windows. Finally, specify which investigations remain online, which need an ID first, and which must wait for archive recovery. Diagnostic delay belongs in the cost discussion.
A deletion policy therefore defines which future questions remain answerable, as well as how much storage is used. Knowing what is irreversibly gone and what remains conditionally recoverable is necessary to calibrate confidence in an investigation.
Interpreting the reported result
Grafana reports approximately 25% greater information density than probabilistic sampling at the same volume. The article does not sufficiently specify the workload and metric to interpret this as a 25% improvement in root-cause accuracy. Nor does a headline reduction in data volume establish the same reduction in bills. It is a vendor test signal, not a uniform benefit across businesses.
A stronger acceptance check combines retained bytes, sample coverage of low-traffic paths, recoverability of known incident evidence, and time spent waiting during investigation. For agent workloads, also check whether a task remains connected across model calls and tool calls. These are engineering evaluation priorities inferred from the mechanism. The most useful design lesson is to distinguish retained data, searchable data, ID-retrievable data, and offline-recoverable data, then account for the cost of each.