David Morrison (drmorr) · Applied Computing Research Labs · 2026-10-05 · Original article
A scale-out operation can finish while users are still waiting. A node has joined and a Pod has been scheduled, but application startup and queued work remain. The article proposes MTSS—Mean Time to Stop Sucking—to shift attention toward recovery of the user experience. Improving one controller’s timing does not necessarily shorten that experience of degradation.
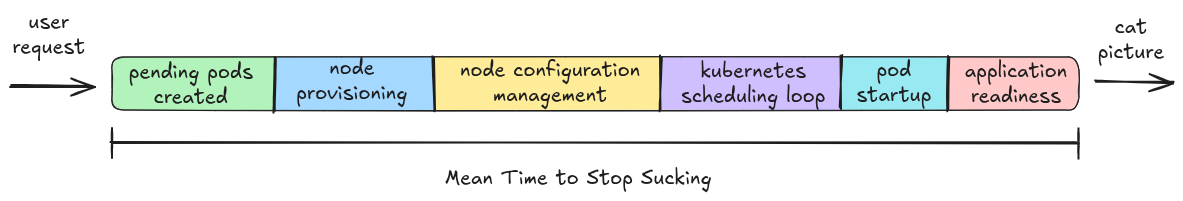
The article’s scale-up illustration. Segment widths should not be read as measured production timings.
Define what counts as recovery
The following is an engineering interpretation of that idea. Its unit of observation is a workload-pressure episode, rather than each newly created Pod.
Let $t_0$ mark the onset of sustained capacity pressure at the ingress together with violation of a predefined user-facing objective. Let $t_r$ be the first time the service meets its objectives again and continues to meet them throughout a following observation window $W$. The episode’s recovery time is:
If an episode never violates the objective, record it as having no degradation and report its share. Do not substitute ordinary scale-out duration for recovery time. Calculate recovery means and quantiles for episodes that actually experienced degradation.
The objective should include latency, errors, and a minimum amount of useful service. Looking only at successful-request latency can make a system that rejects most traffic appear healthy. HTTP success rate alone can miss increasing waits in asynchronous work. For queue consumers, oldest-message age, completion throughput, and backlog are useful complementary observations.
The window prevents a brief improvement from ending the episode. Offline analysis can place the recovery onset at $t_r$, whereas an online observer cannot confirm it before $t_r+W$. Keep those timestamps separate: otherwise changing the confirmation window alone changes the reported recovery speed.
Divide the timeline into attributable stages
| Boundary | What to record | Question it answers |
|---|---|---|
| User-facing pressure begins | Ingress traffic, latency, errors, queue waits | When did business impact begin? |
| A scaling decision appears | Desired replicas and the triggering signal | Did the controller detect pressure promptly? |
| Pods are created and bound | Pod UID, creation and binding timestamps | How long was scheduling or capacity unavailable? |
| Instances can receive traffic | Startup and Ready transitions | When did new replicas begin contributing capacity? |
| Service stabilizes | Business objectives and the confirmation window | Has the user experience actually recovered? |
Karpenter’s karpenter_pods_unbound_time_seconds measures Pod creation to binding. It cannot include pressure detection before creation or application recovery after binding. The current documentation marks it alpha, so check the version deployed before relying on it. Karpenter metrics
Ready is a different boundary. Kubernetes readiness probes determine whether a container can accept traffic; startup probes accommodate slow initialization. These represent configured health conditions, rather than automatic proof that an end-to-end latency objective is satisfied. Kubernetes probes
Why a Ready service can still be slow
Draining accumulated work is easy to overlook. Consider a simplified queue: when new capacity becomes available, $B$ tasks remain, subsequent arrivals occur at rate $\lambda$, and processing runs at rate $\mu$. If both rates are approximately constant and $\mu>\lambda$, the approximate drain time is:
This is a simplifying derivation, not an experimental result from the article. If processing capacity only slightly exceeds arrivals, the backlog can disappear slowly despite successful scaling. If $\mu\leq\lambda$, waiting alone will not empty the queue. Real systems also have variable task lengths, retries, and shared downstream constraints; this expression is not a precise predictor for those settings.
An empty queue is not a universal recovery criterion. The model explains why accumulated work can lengthen the tail; the agreed business indicators still determine the endpoint.
That distinction separates two investigations: whether capacity arrived promptly, and whether it became effective enough after arrival. Optimizing node startup without observing throughput and backlog can simply move the waiting time to another stage.
Join events without forcing one giant trace
Requests, HPA decisions, and node creation are not naturally one synchronous call chain. Many requests may collectively trigger one scaling action, and that action may create several Pods. A single parent-child tree can hide this many-to-many structure.
One implementation is an episode record that associates the workload, namespace, scaling object, Pod UIDs, node identities, and time window. Request traces describe the user path; control-plane events explain capacity changes. OpenTelemetry span links can represent relationships that do not fit ordinary parent-child nesting. Installing tracing alone, however, does not automatically instrument autoscaling control-plane events. OpenTelemetry Traces
Record where timestamps originate and how much collection delay they may include. Several nodes provisioning concurrently are not a sequence whose durations can simply be added. Nor can independently calculated stage P95s be summed into an end-to-end P95. Preserve the individual episode timelines before aggregating across episodes, so that total duration and bottlenecks remain distinguishable.
Know which control loop a setting changes
HPA runs periodically, and reaction also depends on metric collection and delivery. A faster loop reduces only part of the delay. Querying an already stale signal more frequently may still fail to detect pressure promptly. How HPA works
KEDA distinguishes activation from zero and scaling an already running workload. KEDA handles trigger checking for 0-to-1 activation; 1-to-N scaling still involves HPA metric queries and control. Reducing pollingInterval therefore does not uniformly accelerate the complete path. Likewise, cooldownPeriod, which concerns scaling to zero, is not a scale-up waiting period. KEDA ScaledObject
Signal selection also requires an experiment. For queued workloads, one testable hypothesis is that queue age or arrivals reveal pressure earlier than average CPU. Whether that helps depends on task costs and the bottleneck. Replay the same traffic and compare trigger timing, recovery, and extra resource use instead of assuming that one signal is always superior.
Evaluate the outcome, not just the action
Start with step changes, short bursts, and gradual ramps. Separate cases with warm spare capacity from those that require new nodes. Change one factor at a time—such as control timing, node initialization, or application warm-up—and record the recovery-time distribution, affected requests, and resource cost.
Do not drop episodes that remain unrecovered at the observation deadline. Report their fraction separately and mark the observations as unfinished. Otherwise, an unreliable policy can appear fast because the mean includes only its successful episodes.
This gives chaos experiments a concrete objective: introduce controlled delays in image pulls, node registration, or application warm-up, then observe how the impact propagates to users. Separate insufficient capacity from application faults. More replicas do not automatically repair incorrect logic or a failed downstream dependency.
The useful comparison is whether degradation lasts less time and causes less harm under the same workload and resource constraints. The article supplies the perspective; the episode definition, stability window, and experimental procedure above are a proposed way to make it testable.