Original: Building a High-Performance and Portable vLLM Linear Backend with Helion
Sean Chen (Red Hat), Shangdi Yu (PyTorch, Meta Platforms) · First published 2026-10-02
Why one implementation still needs several execution strategies
LLM linear layers perform many matrix multiplications, and general-purpose high-performance libraries have benefited from years of optimization. Inference shapes nevertheless vary: prefill processes more tokens, while small decode matrices can struggle to occupy the GPU. The best tiling, parallelism, and algorithmic variant are not fixed even for the same mathematical operation. This article turns those shape-dependent choices into searchable parameters and integrates them into a real vLLM serving path.
Helion offers a tile-programming interface close to PyTorch. Developers maintain one computation while an autotuner searches configurations, reducing the need to handwrite separate kernels and dispatch rules for each shape. This implementation uses Helion’s Triton backend, with measurements concentrated on NVIDIA Hopper and dense models. Portability as a design goal does not establish equal end-to-end gains on other hardware.
Put algorithm selection inside the search space
Standard GEMM distributes work over the output matrix. When M or N is small, there may be too few parallel blocks. Split-K divides the reduction dimension among more blocks and combines their partial results, increasing parallelism but adding initialization and aggregation costs. Swap-AB uses a transpose identity to reverse operand orientation and enable more favorable tiling for small M. Either can help; neither wins on every shape.
The article’s illustrative implementation expresses Standard GEMM, Split-K, and Swap-AB together. The split_k parameter searches powers of two from 1 through 256, while swap_ab is Boolean; both are measured alongside lower-level configurations. The example zeroes the output and uses atomic addition when splitting K. Quantized variants add scaling logic. The optimization selects an execution strategy for a particular shape; an identical mathematical formula should not be confused with an identical numerical accumulation path.
Three formats are covered. FP8_Dynamic uses per-token activation and per-channel weight scaling. W8A8_INT8 uses INT8 with the same scaling granularity. Block_FP8 uses 1×128 activation scaling and 128×128 weight scaling. Formats and scaling granularities are experimental conditions, so a gain for one cannot be assigned to quantized inference in general.
Hybrid dispatch addresses runtime overhead
CPU dispatch and launch costs can erase the benefit of a faster GPU kernel. The authors therefore use Helion only for small shapes covered by CUDA Graph replay, returning larger shapes to the default backend. This also narrows the set of shapes that must be tuned and maintained.
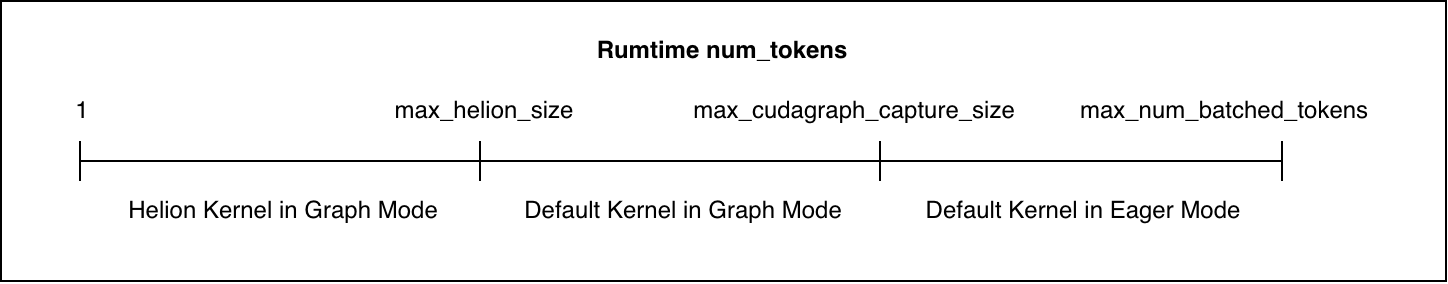
Reading the diagram: from left to right, execution uses Helion under graph replay, the default kernel under graph replay, then the default eager path beyond graph coverage. These thresholds are not universal hardware constants.
This work sets max_helion_size=32 and tunes token counts 1, 2, 4, 8, 16, 24, and 32 separately for each model’s corresponding GEMM shapes. Tuning measurements also enable CUDA Graphs, bringing the search conditions closer to deployment. Falling back for larger shapes does not imply that they cannot be optimized; the present strategy concentrates effort on decode shapes with promising returns.
The search uses LLMSeededLFBOTreeSearch: an LLM supplies candidate seeds, and subsequent search selects configurations through benchmarking. The article names Claude Opus 4.8 as the seed model. A model suggestion does not establish performance; measurements on target shapes determine the choice. The article does not establish a general advantage across alternative seed models.
Preserve the conditions when moving from kernels to serving
All performance experiments use one H100 80GB HBM3 GPU. Models include Qwen3-1.7B, 4B, 8B, 14B, and 32B, plus Qwen3.8-27B. Reported geometric-mean kernel speedups are 1.110× for FP8_Dynamic over CUTLASS, 1.178× for W8A8_INT8 over CUTLASS, and 1.149× and 1.177× for Block_FP8 over FlashInfer and DeepGEMM respectively. These aggregate multiple input shapes; individual shapes vary.
End-to-end evaluation uses ShareGPT, tensor parallelism of one, a maximum of 32 sequences, and disabled prefix caching, comparing the default and Helion linear backends. The authors report throughput gains above 10% for some workloads. This does not mean every model is at least 10% faster, or that kernel speedups translate directly into whole-system speedups: attention, scheduling, and other operators still consume time.
Disabling prefix caching helps isolate this backend comparison, whereas real multi-turn agents often depend on reuse. The engineering interpretation here is to treat the result as a candidate optimization for small concurrency and the evaluated quantization formats, then compare under the deployment’s own context distribution, caching configuration, and concurrency. The result cannot be directly extrapolated to high concurrency, MoE, or another GPU.
Who pays for tuning?
Fine-grained searches can take hours. CUDA Graph capture during vLLM startup also triggers JIT compilation and increases cold-start latency. Cached compiled artifacts help subsequent warm starts but do not eliminate first-time preparation. Shipping many model-specific configurations improves convenience while increasing upstream validation and maintenance work.
At publication, the implementation and pre-tuned configurations are in the authors’ vLLM fork, with upstream integration discussed in an RFC. The authors propose maintaining kernels and basic functional configurations upstream while leaving workload-specific tuning to deployment owners. This exchanges offline effort for runtime gains; its value depends on deployment lifetime, model-change frequency, and configuration reuse.
Bring the serving distribution back into tuning decisions
Before adoption, establish which calls actually enter the optimized range. The maximum sequence count limits the number of sequences participating in serving, while runtime token count also depends on the scheduling phase. The article tunes shapes supported by graph capture and measures small-concurrency workloads. Seeing the same value of 32 in a deployment setting does not establish that every online matrix multiplication follows the same path. Actual shape distribution and dispatch coverage are the relevant checks.
Account separately for preparation and steady-state execution. A fixed model serving for a long time can amortize offline search and initial compilation across many requests. Frequent model changes or instance recreation make preparation more significant. Compilation caching determines whether existing artifacts can be reused; autotuning determines whether a configuration suits the target shape. Neither replaces the other. This is engineering reasoning from the article’s cost categories, not an author-measured break-even result.
Finally, retain the default backend as the comparison and observe the complete serving path. If kernel timings improve but user-visible latency and throughput do not, inspect optimized-path coverage and time spent elsewhere before expanding the search space. Record configurations together with hardware, model, quantization, and software version. Changing any of these conditions can require revalidating an earlier optimum. The article provides neither a universal performance guarantee nor a measurement of maintenance cost for every deployment scenario.
Read hybrid dispatch and the evaluation setup before the code. This industrial engineering report shows how a high-level DSL can place multiple algorithmic variants inside one search framework, while tuning, cold starts, and configuration maintenance remain system costs. Blackwell, AMD, TPU, and MoE extensions are future directions in this article, not additional conclusions established by its Hopper measurements.